An improved biomechanics score is not yet evidence of an improved pitcher. Before a development staff credits a training block, it needs to establish that the baseline and follow-up measurements can be compared.
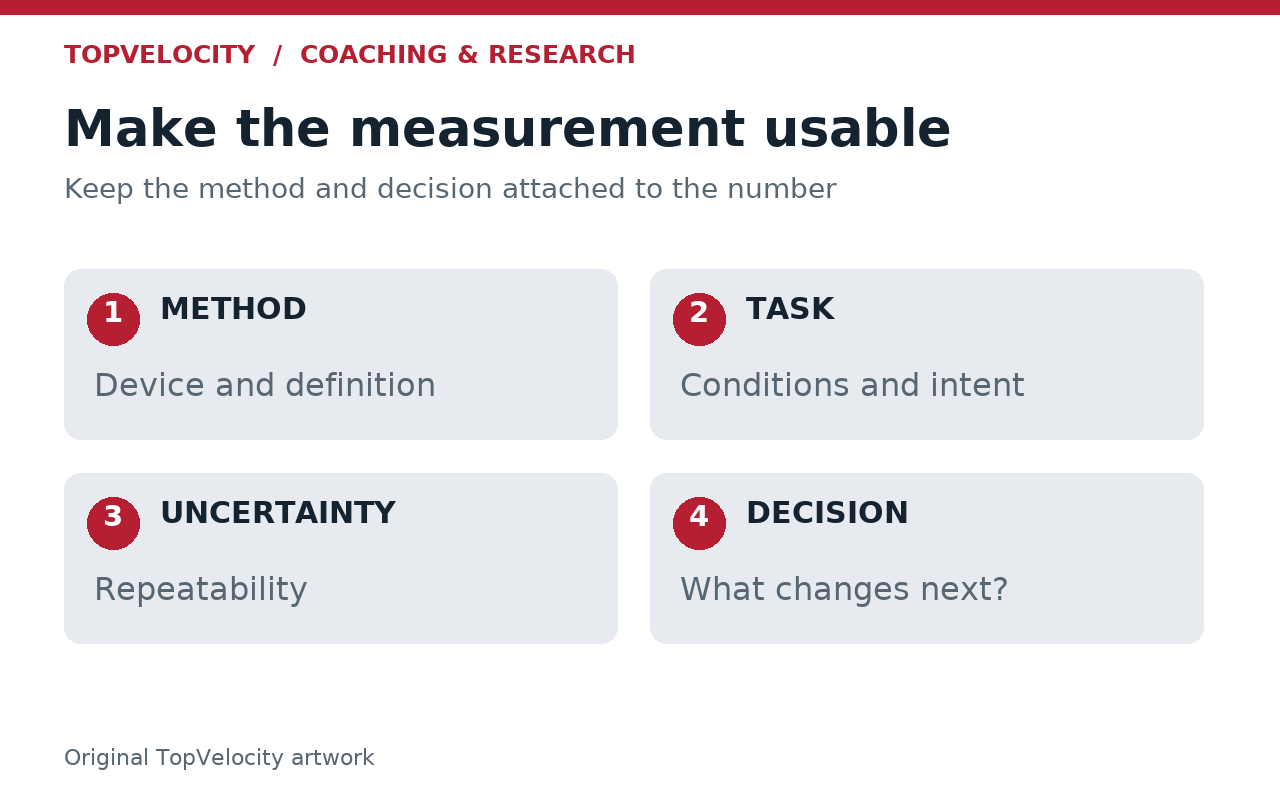
Four distinct parts of a measurement record: method, task, uncertainty and coaching decision.
For a professional organization, a useful biomechanics report must distinguish an athlete changing from the measurement changing. That requires more than a high correlation, a favorable percentile or a cleaner-looking delivery. It requires a documented method and a defensible threshold for interpreting that particular metric.
A repeatable number can still disagree with another system
Three questions often become one claim that a technology is “validated.” Keep them separate:
- Correlation: Do two measurements tend to move together?
- Agreement: Do they produce sufficiently similar values for the comparison we want to make?
- Repeatability: Under comparable conditions, how much does the result vary when we repeat the measurement?
In a study of 30 pitchers, Fleisig and colleagues compared simultaneous markerless and marker-based recordings of 275 fastballs. Movement waveforms were similar, yet biases in individual angle measurements ranged from zero to 16 degrees. The authors recommended system-specific reference ranges. That finding supports keeping the measurement method attached to the number; it does not establish an error range for every camera system. Read the method-comparison study.
A 2026 study provides another useful distinction. In 29 collegiate pitchers, a wearable sleeve and a markerless reference system each produced high reliability coefficients, while their agreement failed the investigators’ predefined criteria. The lesson concerns the question being tested: repeatability alone cannot establish that two methods are interchangeable. These results apply to the systems and protocol studied. Read the construct-validity study.
Give each decision metric a measurement passport
A “measurement passport” is our proposed record of what a number means and when staff can use it. It travels with the result, allowing a pitching coach and an analyst to interpret the same comparison without reconstructing its history.
| Field | Record before interpreting change |
|---|---|
| Decision | The coaching question, proposed action and evidence that would change the plan. |
| Metric | Definition, units, sign convention, anatomical model and event used to calculate it. |
| Capture | Hardware, software version, calibration and processing settings. |
| Throwing task | Pitch type, ball, mound, target, intent, warm-up and relevant session context. |
| Sample | Athletes, sessions and pitches per session; valid-trial and exclusion rules. |
| Summary | Whether the reported value is a mean, median, peak or distribution; how trial variation is retained. |
| Uncertainty | Repeat-session error for this metric and protocol, its confidence interval, and known missing-data limits. |
| Decision rule | The change considered measurable, the improvement considered useful, and the follow-up required. |
An empty field is useful information. If repeat-session error is unknown, the appropriate output may be “observe and retest,” rather than a precise claim that a mechanical adjustment succeeded.
Build the baseline around the comparison you intend to make
Start with the athlete and the task. A maximum-effort fastball from a regulation mound and an underload drill can each answer a development question, but combining their values conceals which question the comparison answers. Likewise, averaging every pitch can obscure a change in pitch selection or intent.
Define the protocol before testing. Keep the key conditions compatible between sessions and record meaningful deviations. Apply the same valid-trial rules to baseline and follow-up. Report how many throws were attempted, captured and retained, so a favorable average cannot hide selective missingness.
Evaluate repeatability at the level used for decisions. A repeatable single-trial measurement does not automatically establish repeatability of a session’s peak, and repeated throws within one session do not establish stability across days. Estimate error for the actual summary statistic and testing schedule.
A detectable change and a worthwhile change are also different. Standard error of measurement can inform an uncertainty threshold under appropriate assumptions; crossing it does not establish that the change helps a pitcher compete. Conversely, a potentially useful change smaller than the current uncertainty may require better measurement or additional observation. Weir’s methods paper explains reliability and measurement error.
More pitches do not create more independent athletes
A large pitch file can still represent a small number of people. Retain athlete and session identifiers, and use an analysis that accounts for repeated observations. If the intended claim is that a model works on unfamiliar pitchers, evaluate it on athletes withheld from model development—not merely different throws from athletes it has already seen.
Context needs similar care. A 2025 study compared 30 collegiate pitchers recorded in a laboratory with 30 recorded in games. Variability was broadly similar across the assessed measures, while mean values differed. Because both the groups and capture methods differed, the study cannot isolate a game-environment effect. It illustrates why compatible context matters; it does not show that laboratory assessment lacks value. Read the laboratory and game comparison.
Turn the result into a coaching decision
For a reported change in pelvis–trunk separation, first check the passport. If the system or event definition changed, establish a compatible comparison before crediting an intervention. If the protocol matches but the observed difference remains within the metric’s established repeat-session uncertainty, retain the observation without calling it a confirmed adaptation.
If the change is distinguishable from expected measurement variation, evaluate its value. Review intended-target error, mound velocity, pitch characteristics and the athlete’s response under the agreed throwing task. Then decide whether to continue, modify or discontinue the coaching experiment. A measurable change can be real without being useful.
The standard TopVelocity proposes
For a professional pitching-development project, TopVelocity proposes agreeing on the measurement passport, coaching question and evaluation criteria with club staff before intervention. This is a proposed operating standard, not a claim that TopVelocity technology has been independently validated by the studies above.
The club should be able to trace each recommendation from observation to uncertainty to coaching action—and see what subsequent evidence would reverse it.
Discuss a professional pitching-development project with a club-defined scope, named decision owners and agreed evaluation criteria.
Sources
- Fleisig GS et al. Comparison of marker-less and marker-based motion capture for baseball pitching kinematics. Sports Biomechanics, 2024; online 2022.
- Wolf J et al. Examination of the Construct Validity of Nextiles Arm Sleeve as a Measure of Peak Elbow-Varus Torque. Journal of Athletic Training, 2026.
- Lerch BG et al. Variability of in-game markerless and laboratory marker-based baseball pitching biomechanics. Journal of Biomechanics, 2025.
- Weir JP. Quantifying test-retest reliability using the intraclass correlation coefficient and the SEM. Journal of Strength and Conditioning Research, 2005. Methods review.